Suprasophis

Intelligent Operations Platform
for Hyperscale AIDC
End-to-end network visibility
and intelligent management for AI clusters

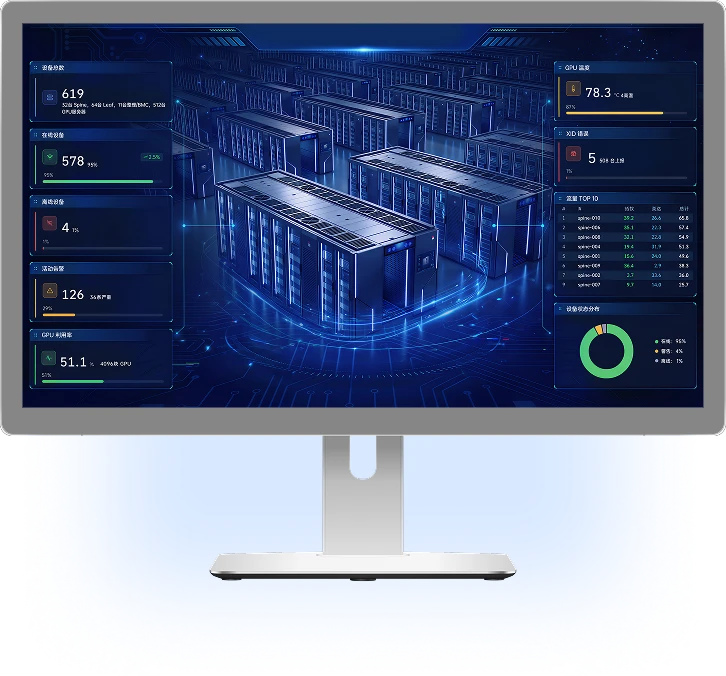
Designed for AI data center operations, the platform unifies operational data across GPUs, networks, and infrastructure, making complex network environments easier to monitor, manage, and optimize

/Network Operations center

An Integrated Network Operations Hub for Monitoring, Analysis, and Lightweight Control

The ChaoHuiLian Intelligent O&M Platform is designed for intelligent computing center network scenarios, integrating monitoring, analysis and lightweight control, with a focus on three core capabilities.

Capabilities.

Ability

Per-second telemetry
Three-tier monitoring dashboard
GPU link health visualization

Pain points.

Solutions

Unable to grasp at a glance the entire network’s health, sub-health, and performance bottlenecks

Capabilities.

Ability

Root Cause Localization
Topology-Linked Alerts
Path-Level Fault Isolation

Pain points.

Solutions

Alert storms flood the screen, and NCCL fault localization takes days.

Capabilities.

Ability

Device Management Configuration
Verification and Changes
ZTP Integration
Pre-training Inspection

Pain points.

Solutions

10,000 devices lose control of configurations; hidden pre-training hazards materialize without prior warning.

/Key Performance Metrics

Key performance at your command

The operations management platform adopts a unified architecture integrating out-of-band and service planes, centrally managing compute, storage, network, and security resources. It incorporates intelligent computing scheduling, intelligent diagnostics, visualized monitoring, and self-healing alerts, achieving full-stack observability and automated O&M, thereby providing an efficient and stable unified management hub for AI inference clusters.

Holistic Insight
01

Unified Management: Integrating Multi-Source Device Management

Unified management of computing, storage, network, and security devices, through device discovery, inventory, topology association, and status collection, brings multi-vendor, multi-type devices under centralized management, forming a unified resource view.

02

Real-time inspection: Proactively identify operational risks

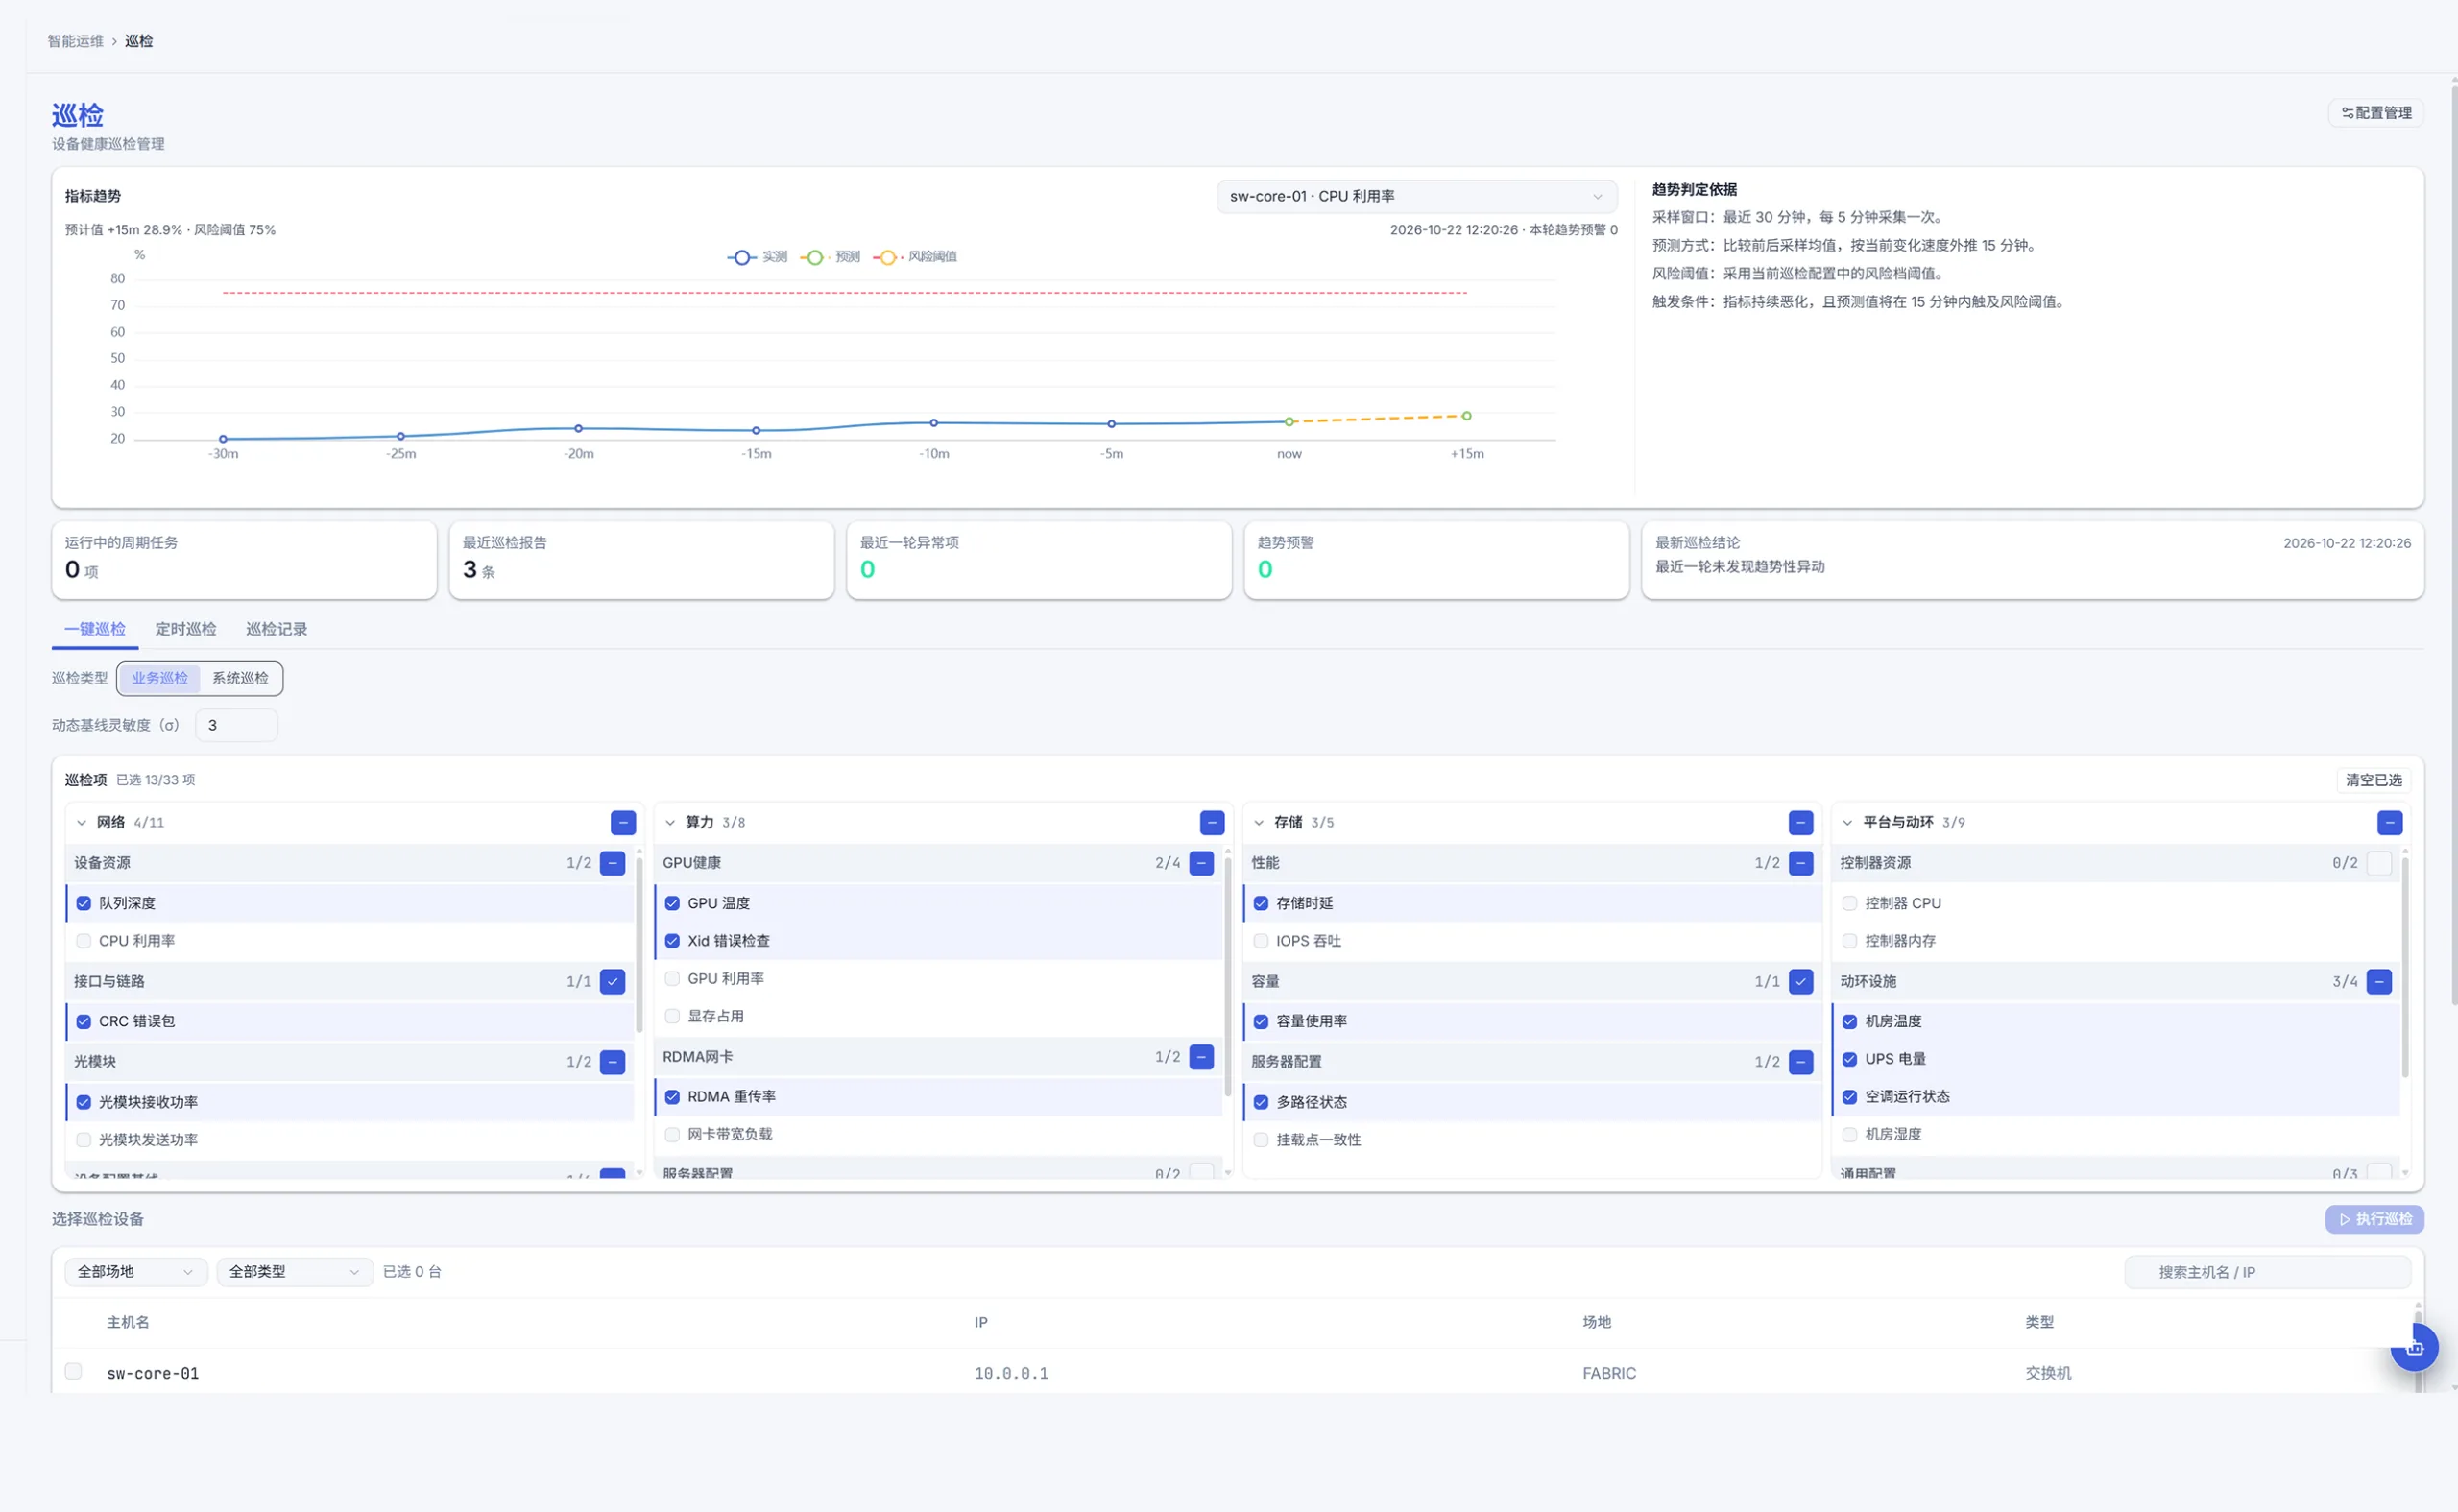
Based on continuous collection of device and link data via Telemetry/API, combined with health checks, configuration verification, and pre-training inspections, port anomalies, link fluctuations, and configuration deviations are identified in real time.

03

Diagnostic Alert: Rapid Fault Root Cause Identification

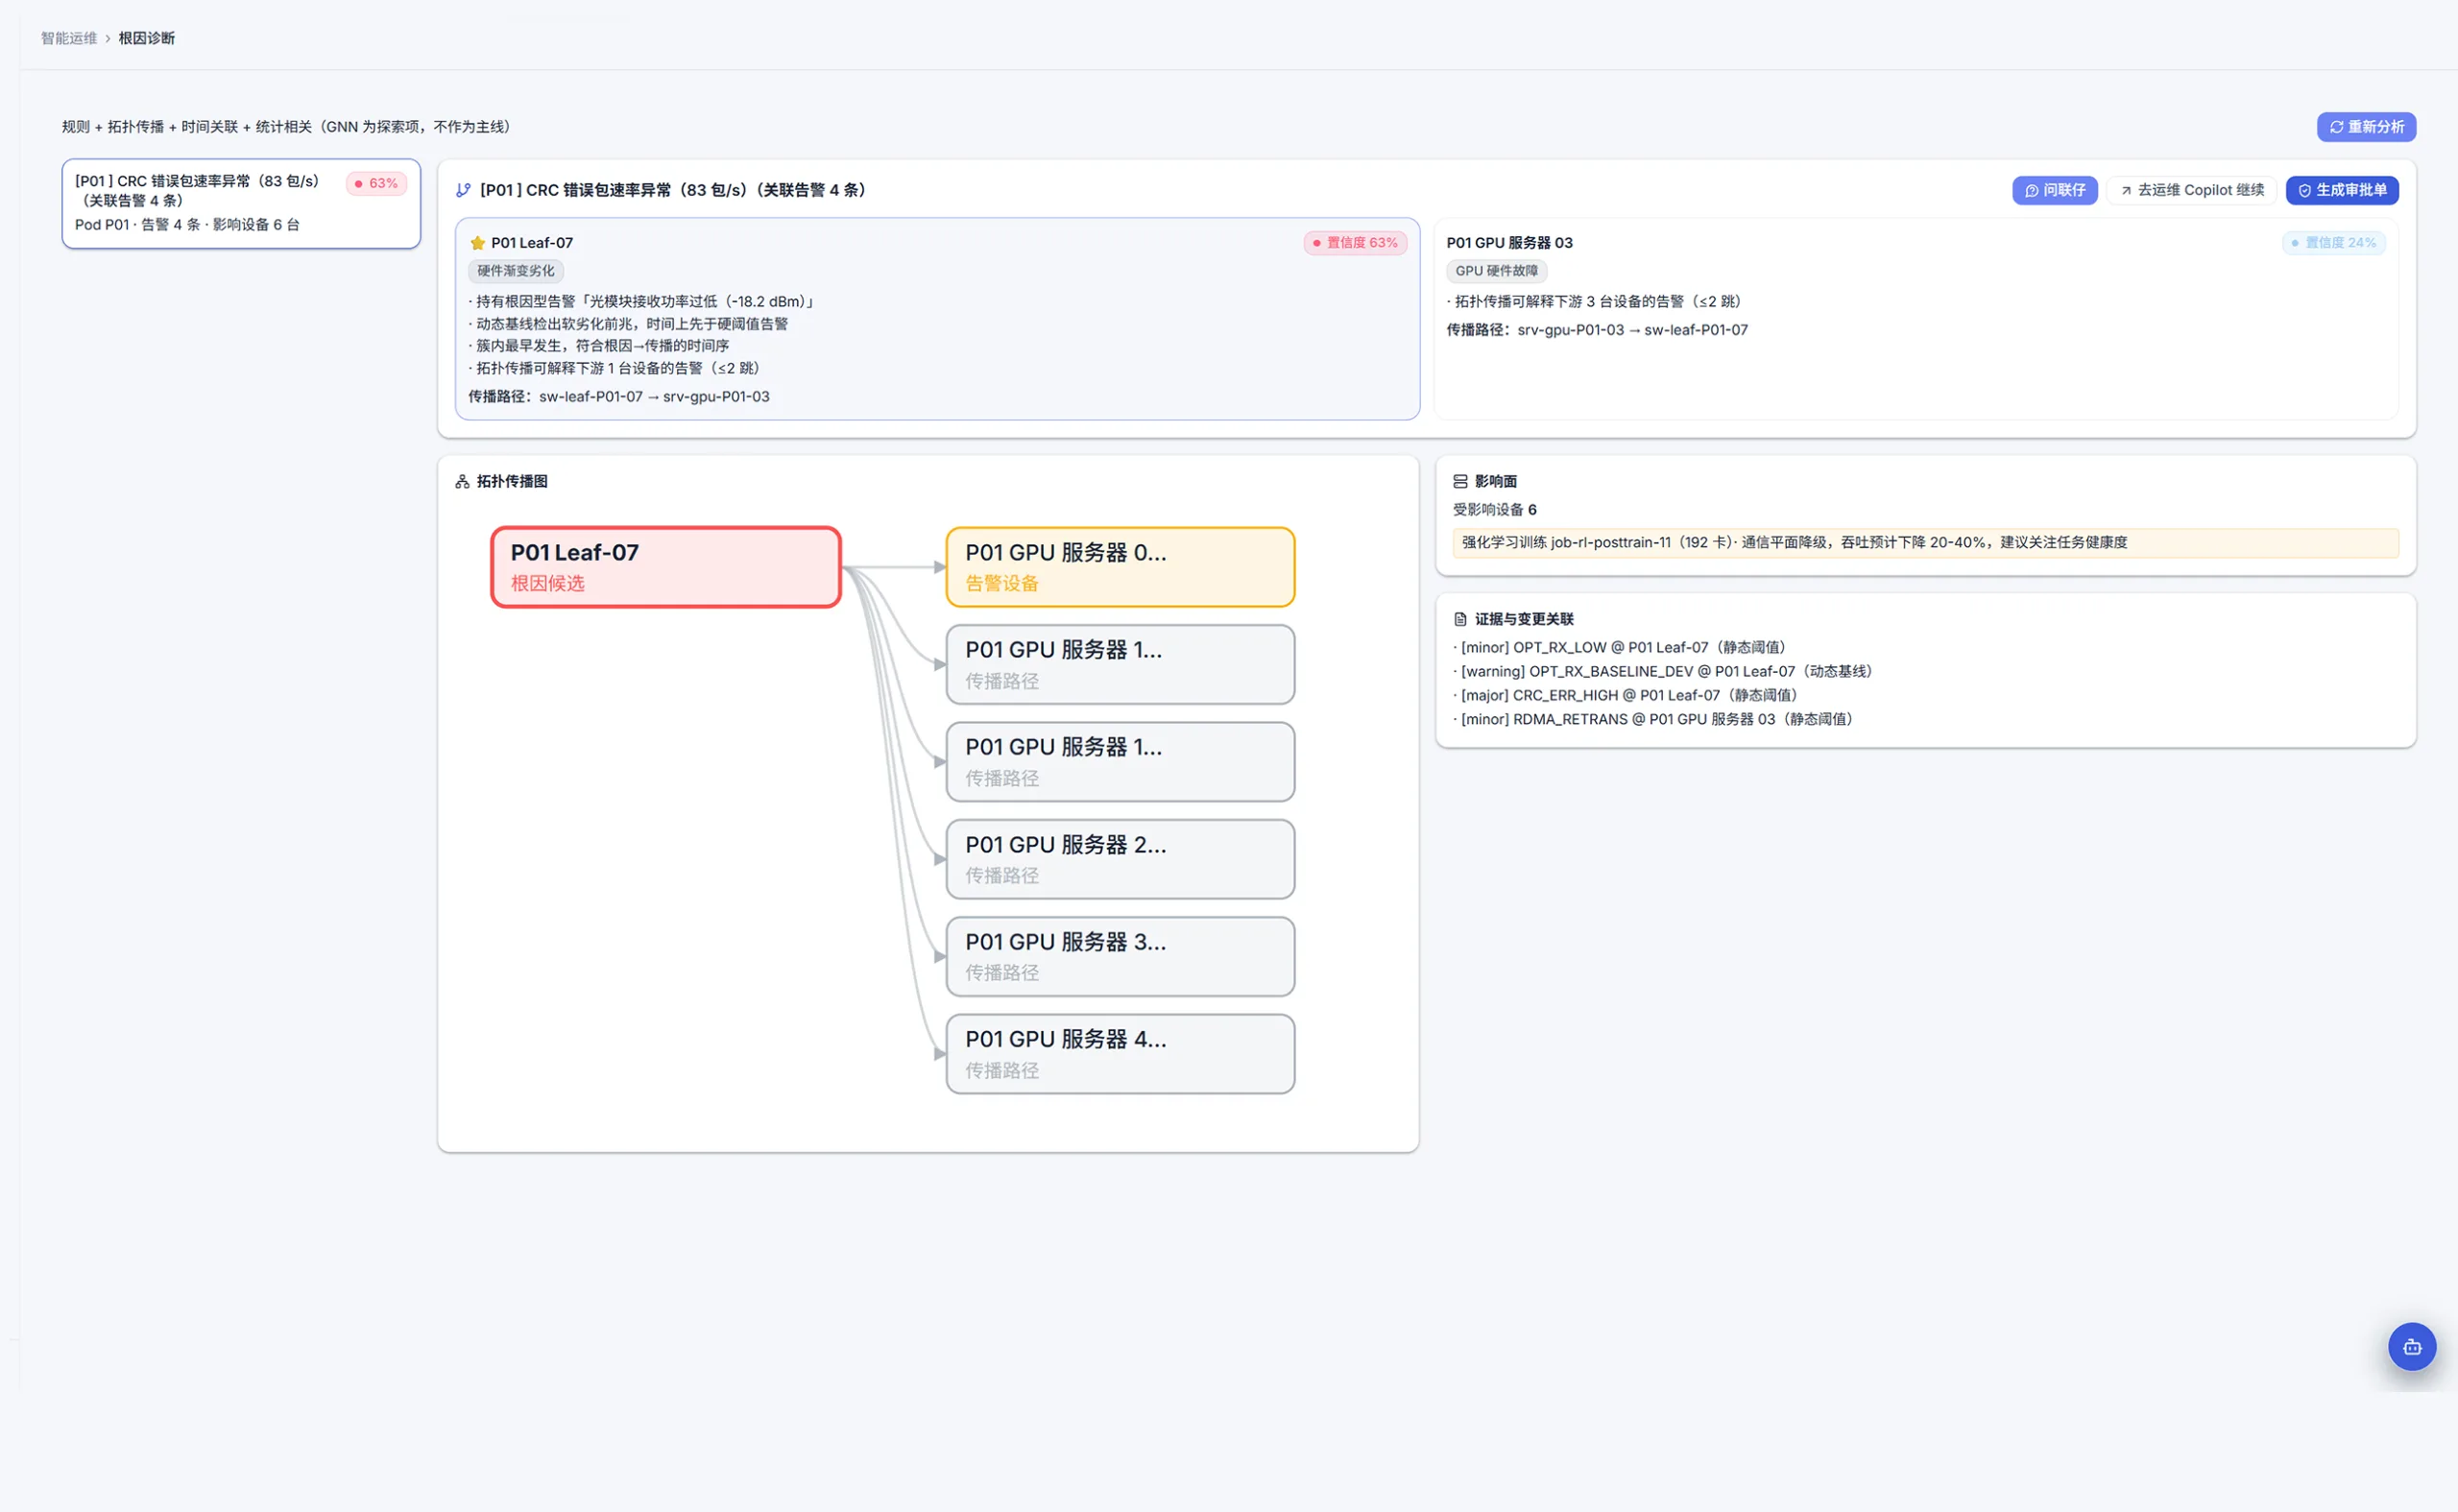
Through topological correlation, alert convergence, and path-level analysis, seemingly scattered alerts are stitched into a complete fault chain; combined with GPU, network, and NCCL runtime data, issues can be quickly identified.

04

Smart Operations: Achieving Automated Closed-Loop Operations

Integrate AI-assisted diagnosis, automated tasks, configuration management, and alerting strategies to link anomaly discovery, analysis, and operations actions; support batch configuration, policy distribution, and automated handling.

05

Permission Governance: Decentralized and Domain-Specific Secure Collaboration

The platform is designed for multi-team collaboration in intelligent computing center operations, providing role- and domain-based access management: different teams are assigned permissions according to their roles and domains, each seeing only the devices and operational scope they are responsible for, thus preventing misoperations and unauthorized access.

06

North-South Openness: Free Access for O&M Capabilities

Southbound, it provides unified management of multi-vendor switches and dynamic environment monitoring equipment, supporting SSH/SNMP/Telemetry, SNMP/Modbus/BACnet protocols to avoid vendor lock-in; northbound, it outputs monitoring, alarm, and topology data via REST and NetConf APIs, interfacing with upper-layer systems such as AIOps, operations dashboards, and ITSM, seamlessly integrating into existing operations systems.

/Tech Highlight

Technical Highlights

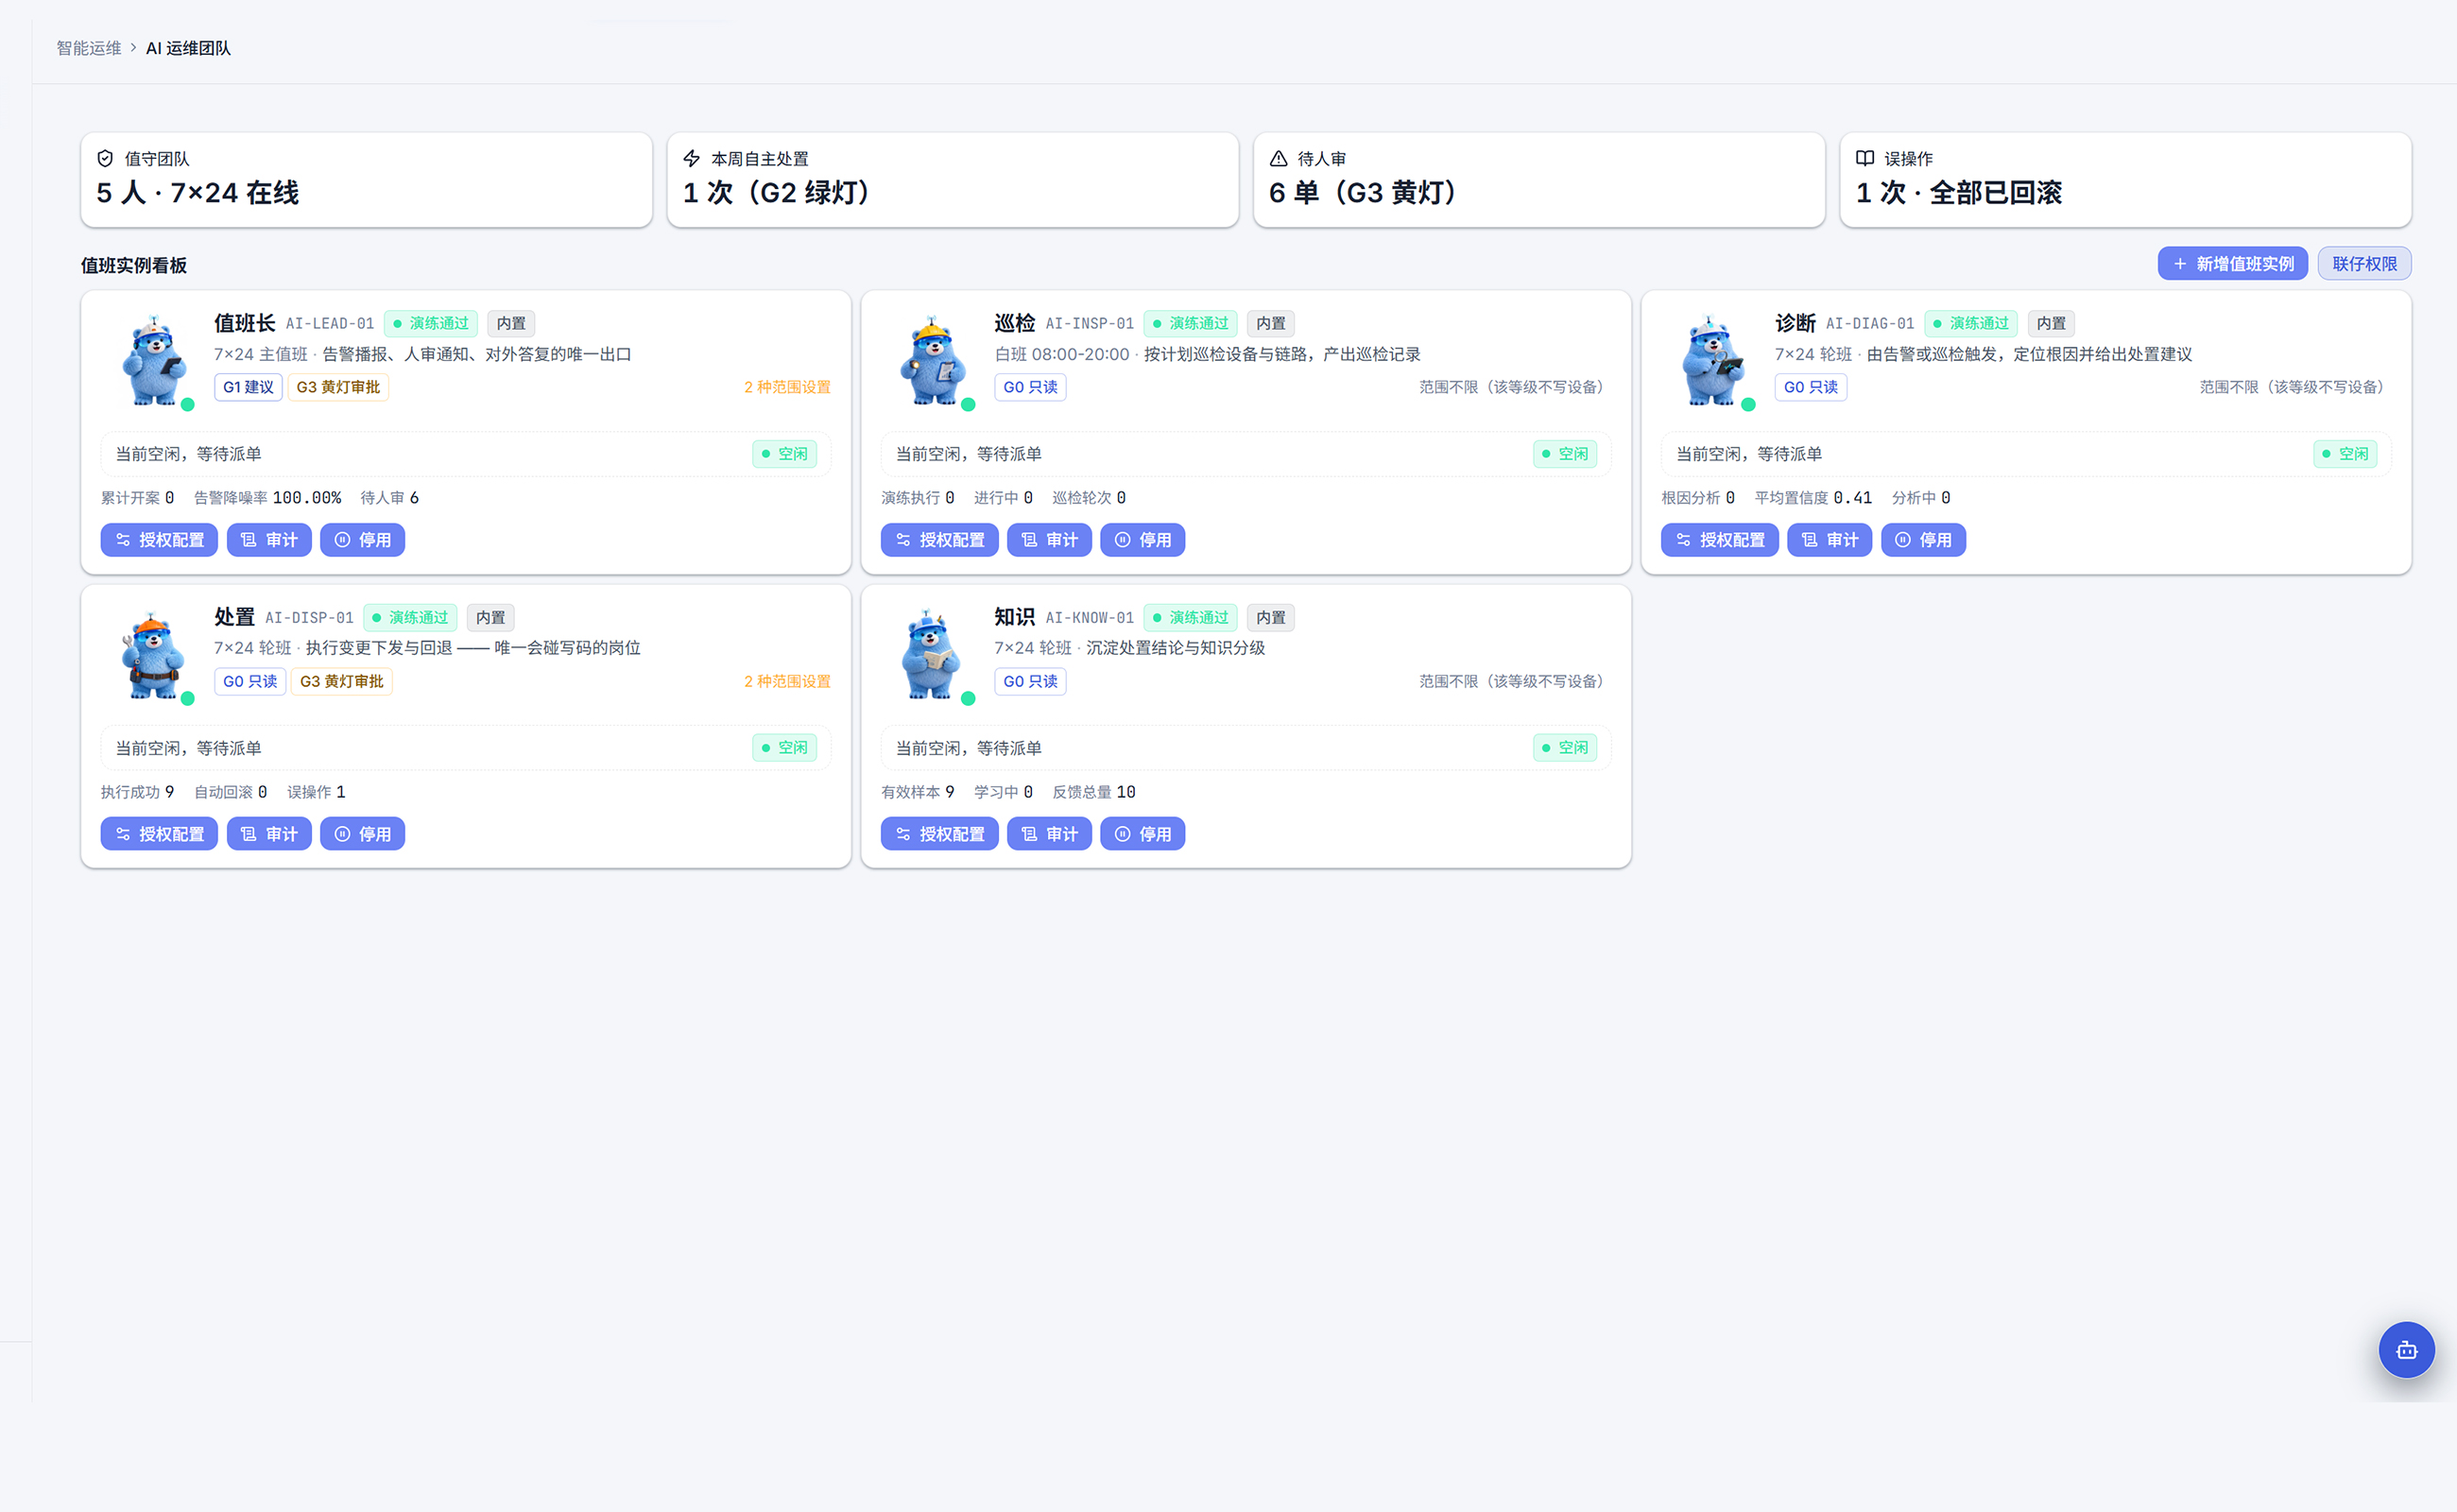
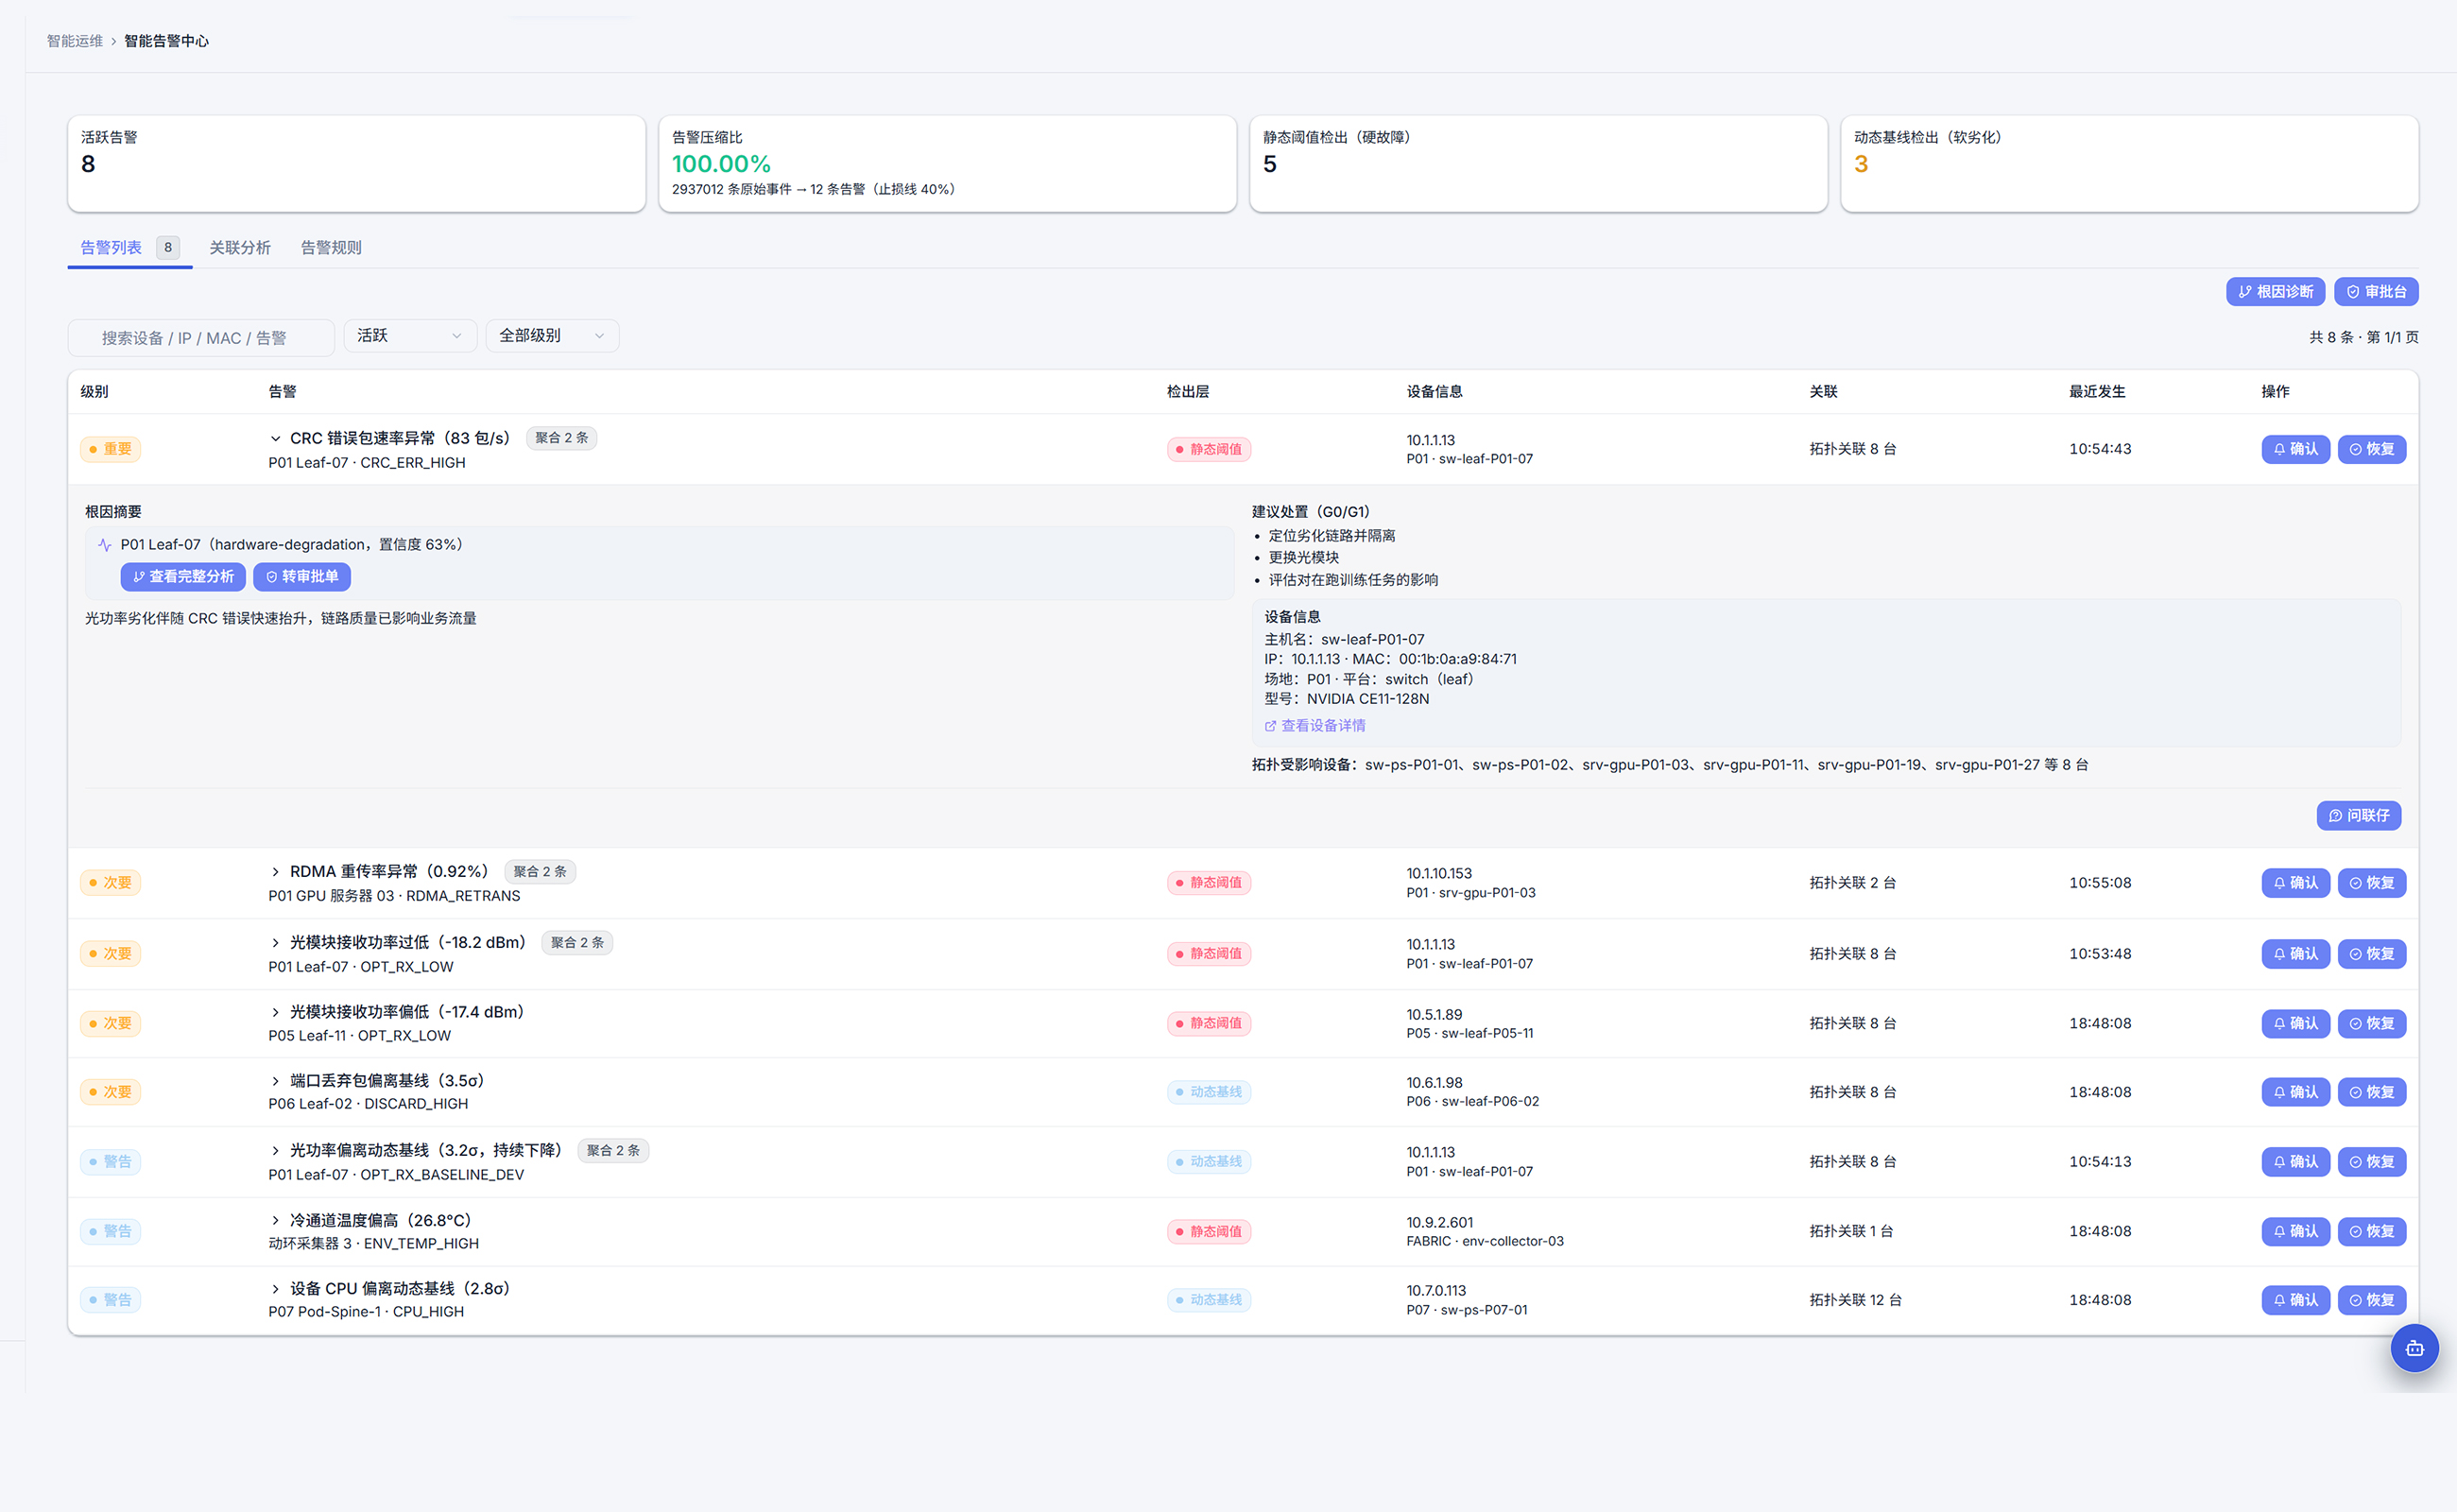
AI On-Site Control Console

A single-screen overview of the computing power network and storage, AI digital workers on collaborative 24/7 duty, supporting natural language interaction. Device operations undergo permission-based risk verification and are executed only after manual confirmation.

Patrol Management

Inspection strategies are flexibly orchestrated by cluster and role. Dual benchmarks identify metric anomalies, early warnings are triggered for trend shifts, and inspection data is consolidated in a closed loop to continuously enhance AI predictive capabilities.

Root cause analysis

Through step-by-step topological link backtracking, automatic alarm clustering infers root causes, accurately identifies the impact scope of GPUs and training tasks, and retains inference evidence for convenient review and handover.

Smart Alert

Same-source alarm aggregation and noise reduction, automatic association of alarms with work orders during change windows, alarm classification and assignment with timeout escalation, proactive root cause tracing for major alarms, and a closed-loop, traceable handling process.

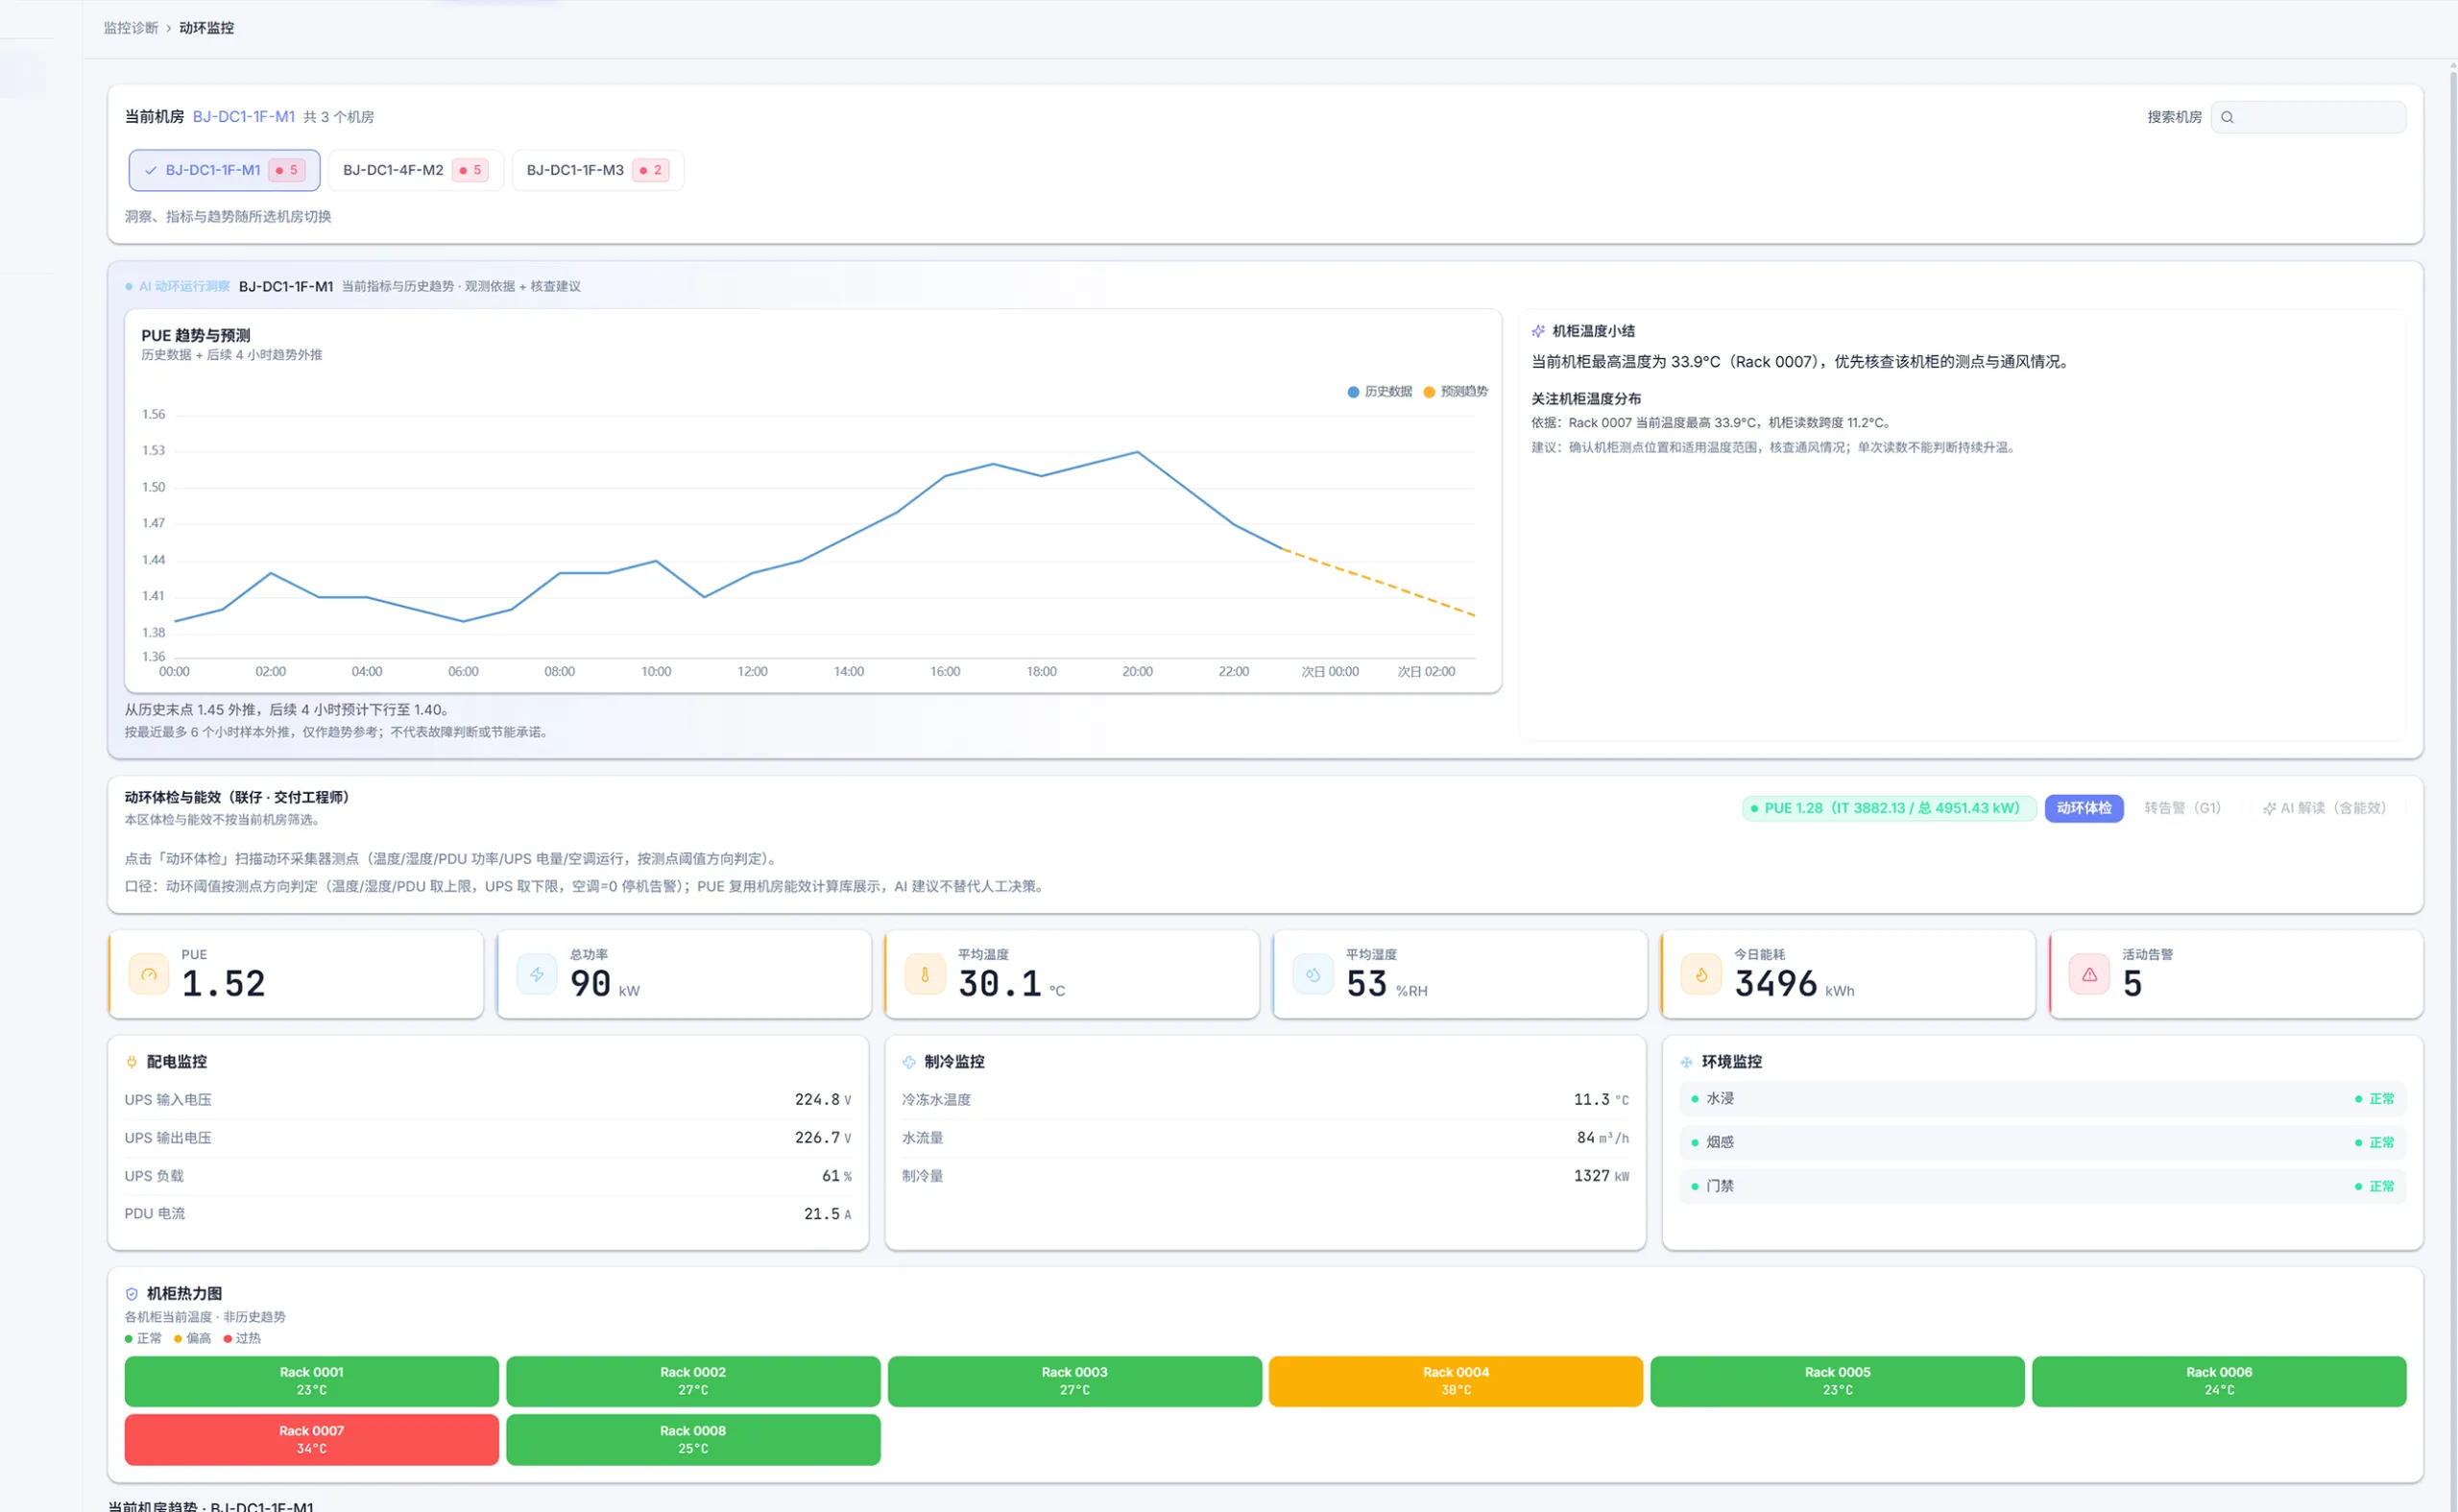
Power and Environment Monitoring

Unified visibility of power distribution, cooling, data center environment, and IT data, supporting multi-level drill-down monitoring, real-time threshold-crossing alarms, load trend forecasting, and early prediction of cooling and power supply risks.

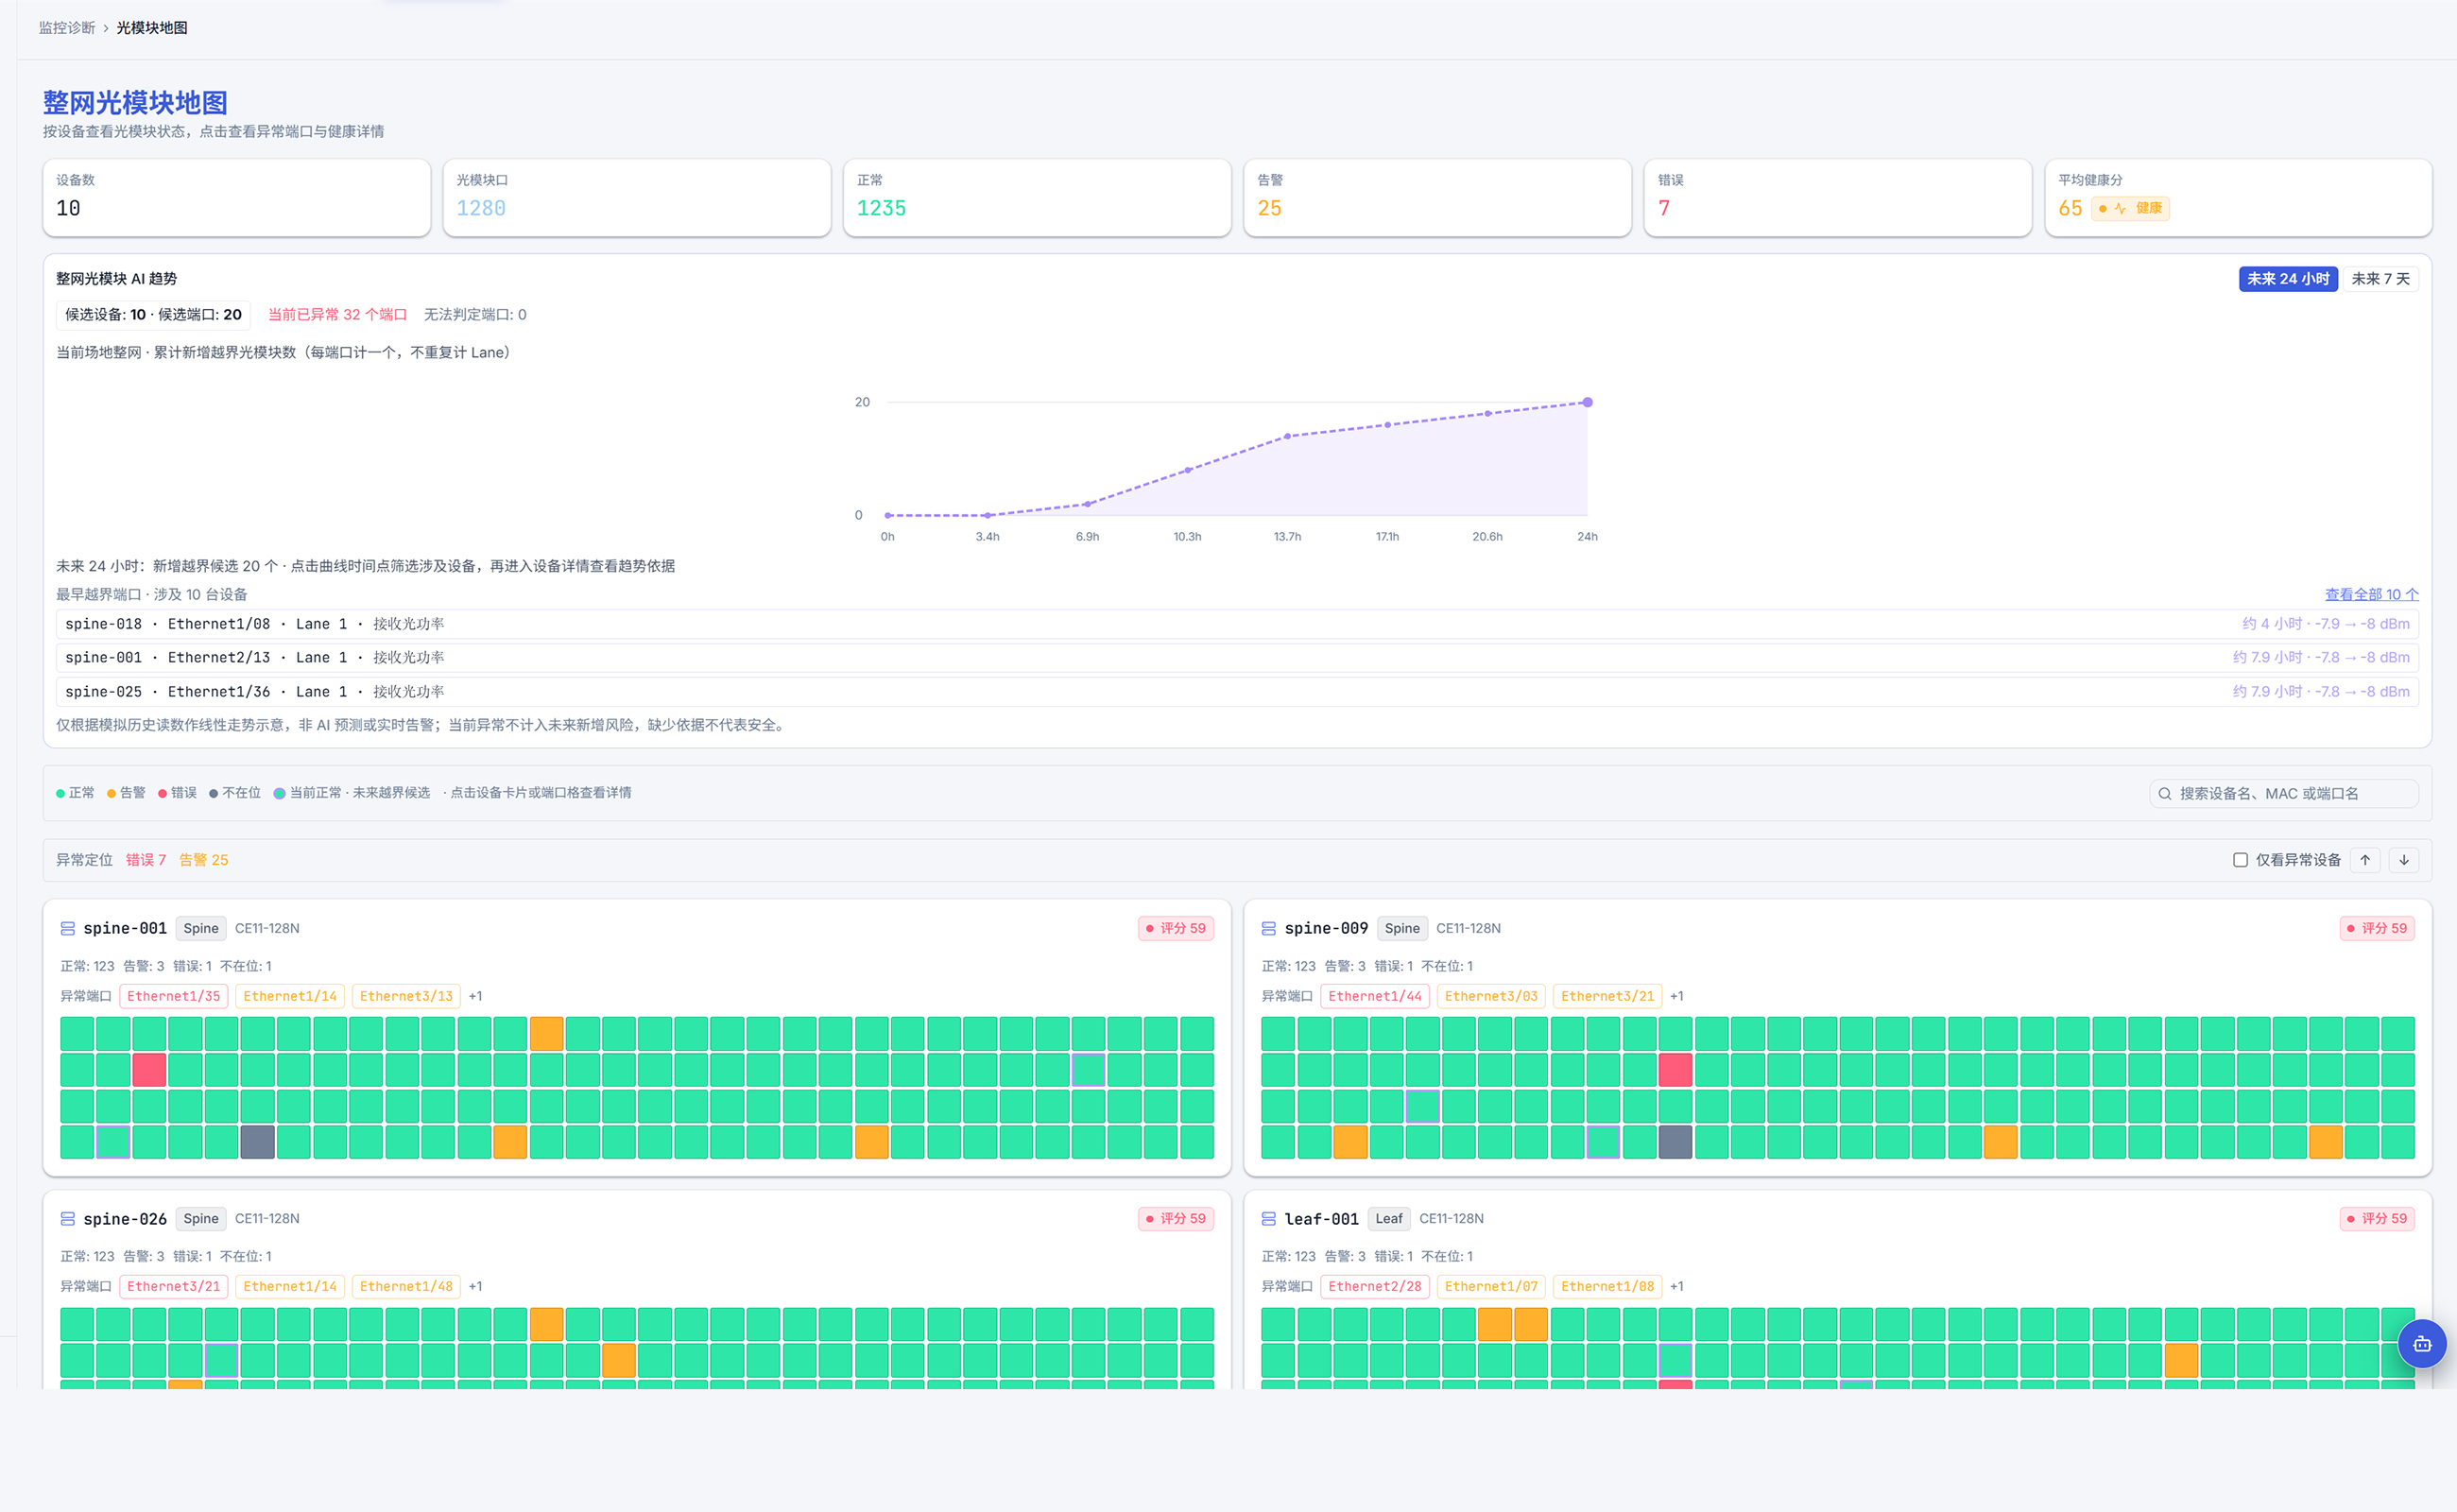
Optical Module Map

Link visualization displays multi-dimensional metrics of optical modules, color-coding identifies indicator drift and degradation, provides early warning of hidden risks, automatically generates replacement work orders, and avoids sudden link failures.

Note: The illustrated data are for demonstration purposes only, solely to display functionality.

/Close the loop of SupraNOS operation

Enable SupraNOS
Closed-Loop O&M

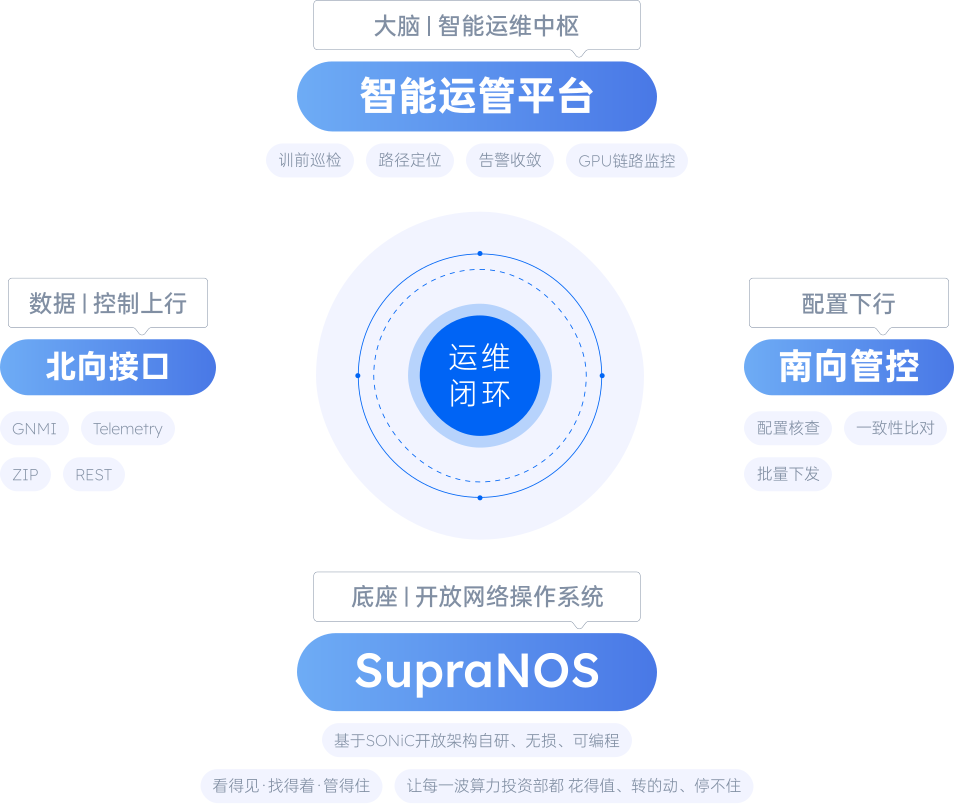
The Super-Converged O&M Platform is not an isolated monitoring tool; together with the SupraNOS operating system, it forms a complete closed loop as the "base + brain" of the intelligent computing network.

Deep Synergy

Telemetry data in, network-wide health view out.

Configuration is deployed from the platform, and SupraNOS implements lossless parameter deployment.

Faults emerge at any layer, and the platform locates them across the entire link.

运维闭环
SUPRANETT

Let's chat about solutions?

Chaohuilian focuses on AI hyperscale cluster infrastructure, maximizing the value of each GPU.