Solutions

End-to-End AI Cluster Networking Solutions
Engineering High-Bandwidth, Low-Latency
Network Architectures for AI at Scale

From thousand-GPU to hundred-thousand-GPU deployments, and across every stage of AI training and inference, Supranett delivers scalable, future-ready networking solutions that evolve with your infrastructure and unlock the full potential of AI computing

AI Training Solutions

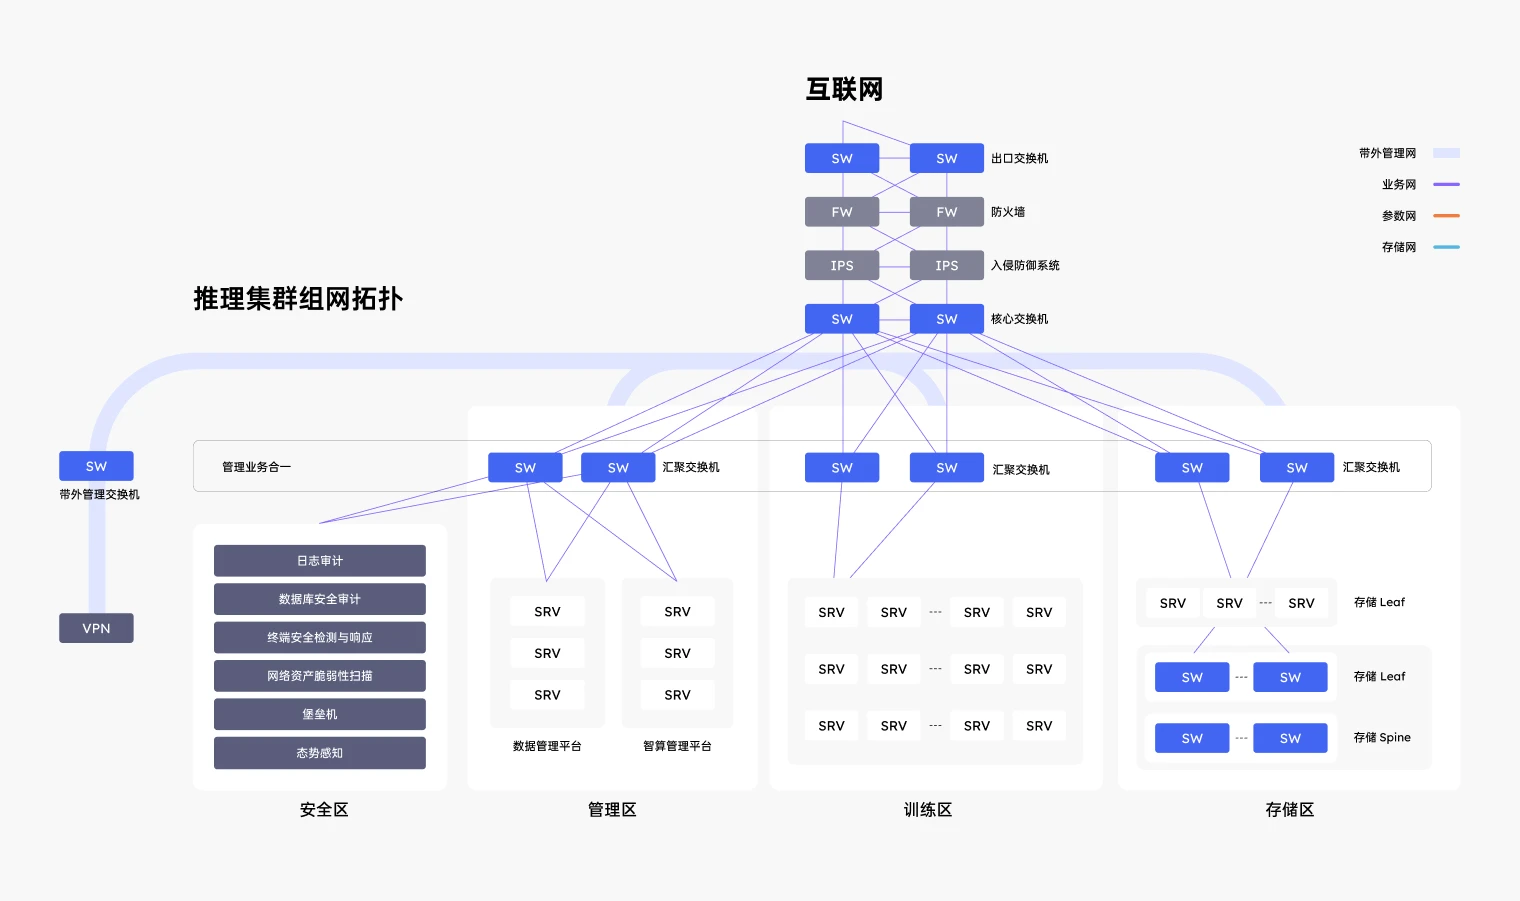
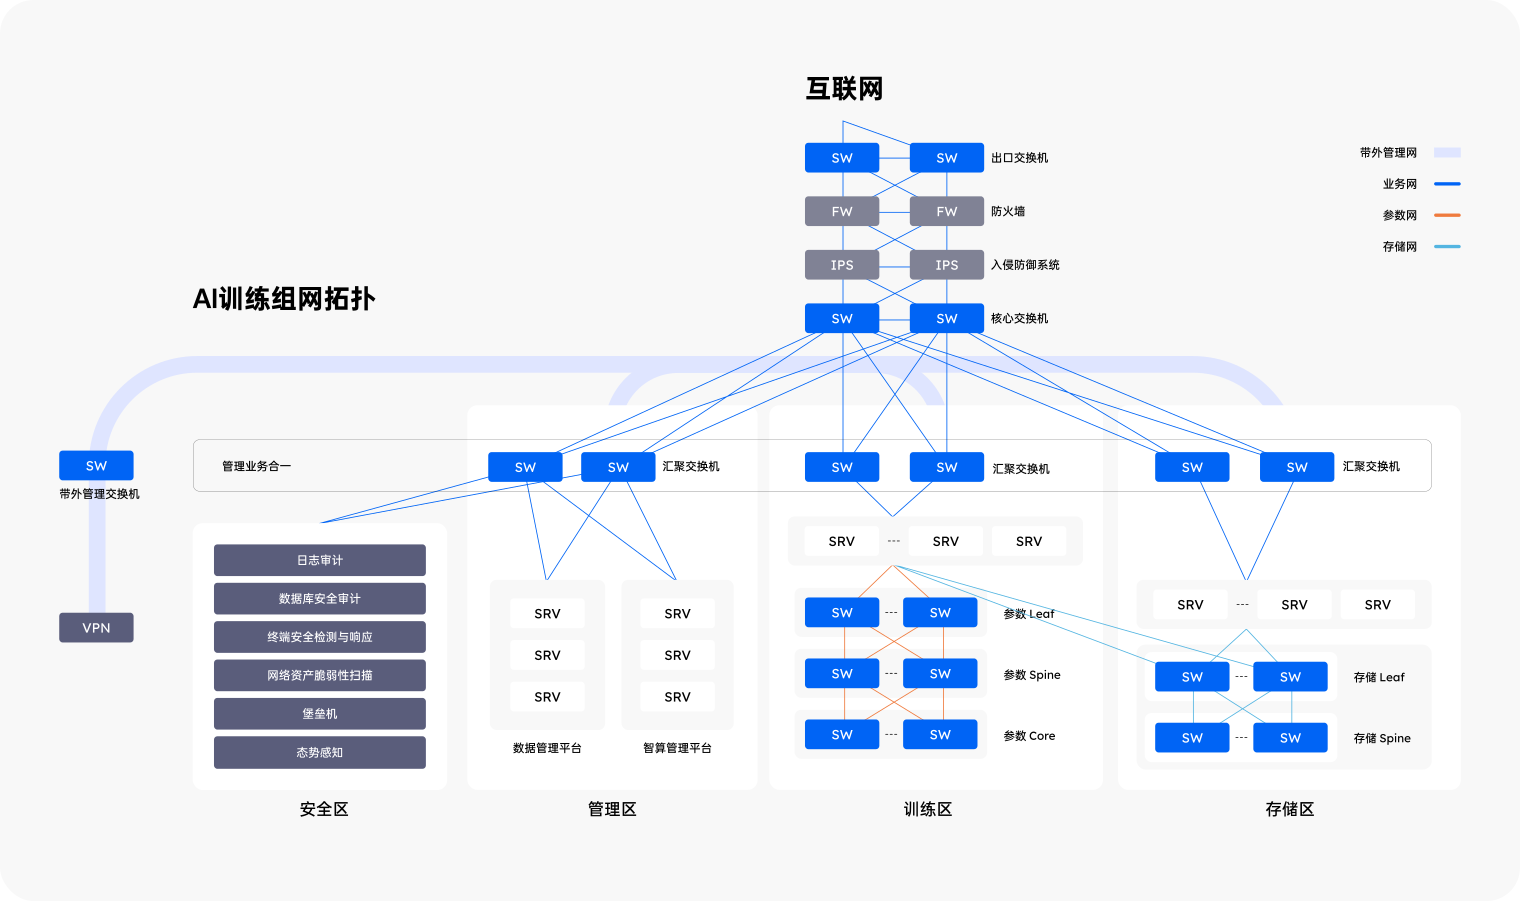
Designed for large model training, a four-domain isolation network for security, management, training, and storage is established. The training zone uses a Leaf-Spine-Core + RDMA lossless Ethernet to ensure high-bandwidth, low-latency communication for tens of thousands of GPU clusters. The storage zone adopts a Spine-Leaf lossless network to reduce data I/O latency. The management zone connects to the Super Computing Integrated Operations Platform, enabling computing power scheduling and full lifecycle data management, supporting training and fine-tuning from thousands to tens of thousands of

AI训练组网拓扑

Inference Cluster Solution

For high-concurrency AI inference, build a dedicated cluster with a single-machine inference zone at its core, using a flat architecture where servers connect directly to aggregation switches to reduce network hops and lower forwarding latency. The storage zone employs hybrid flash storage and a Spine-Leaf network to ensure high-speed loading of model weights and feature data. Combined with four-network separation, the inference service does not require a parameter network, simplifying the network architecture and reducing construction and O&M costs, while meeting the online inference demands

推理集群解决方案

Integrated Training and Inference Solution

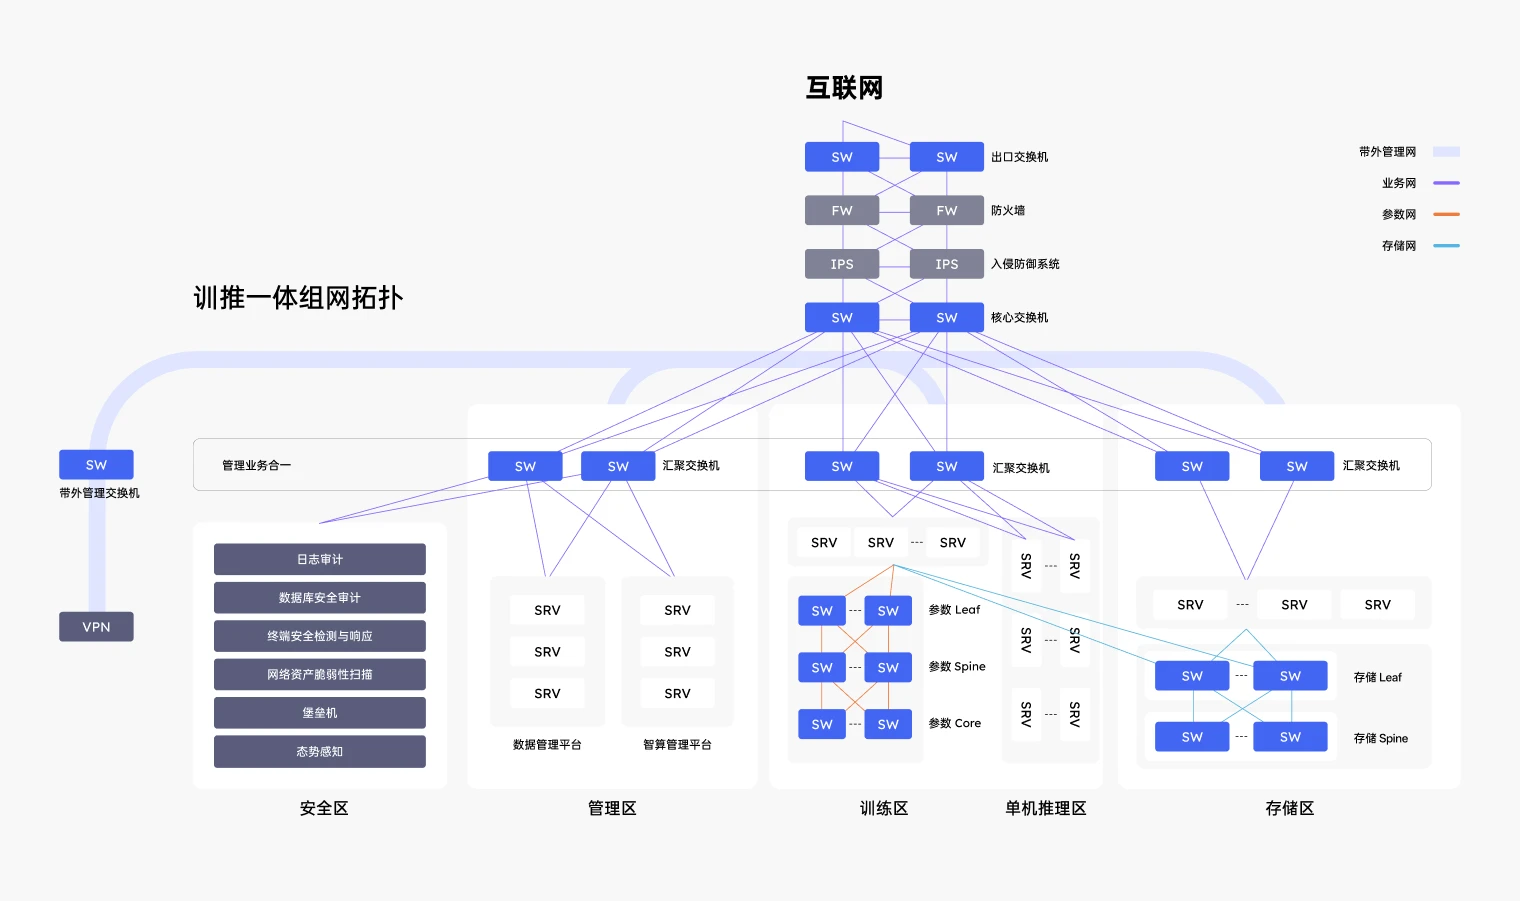
For training-inference integration scenarios, the unified network is divided into a training zone and an inference zone, sharing core switching, security, and storage resources. The training zone supports distributed training, while the inference zone adopts a streamlined architecture with servers directly connected to switches to reduce forwarding latency. Training and inference traffic is isolated through four-network separation, and the storage zone independently employs a Spine‑Leaf network to meet the high‑speed read/write demands of training data and model weights, supporting resource re

训推一体解决方案

Multi-plane solution

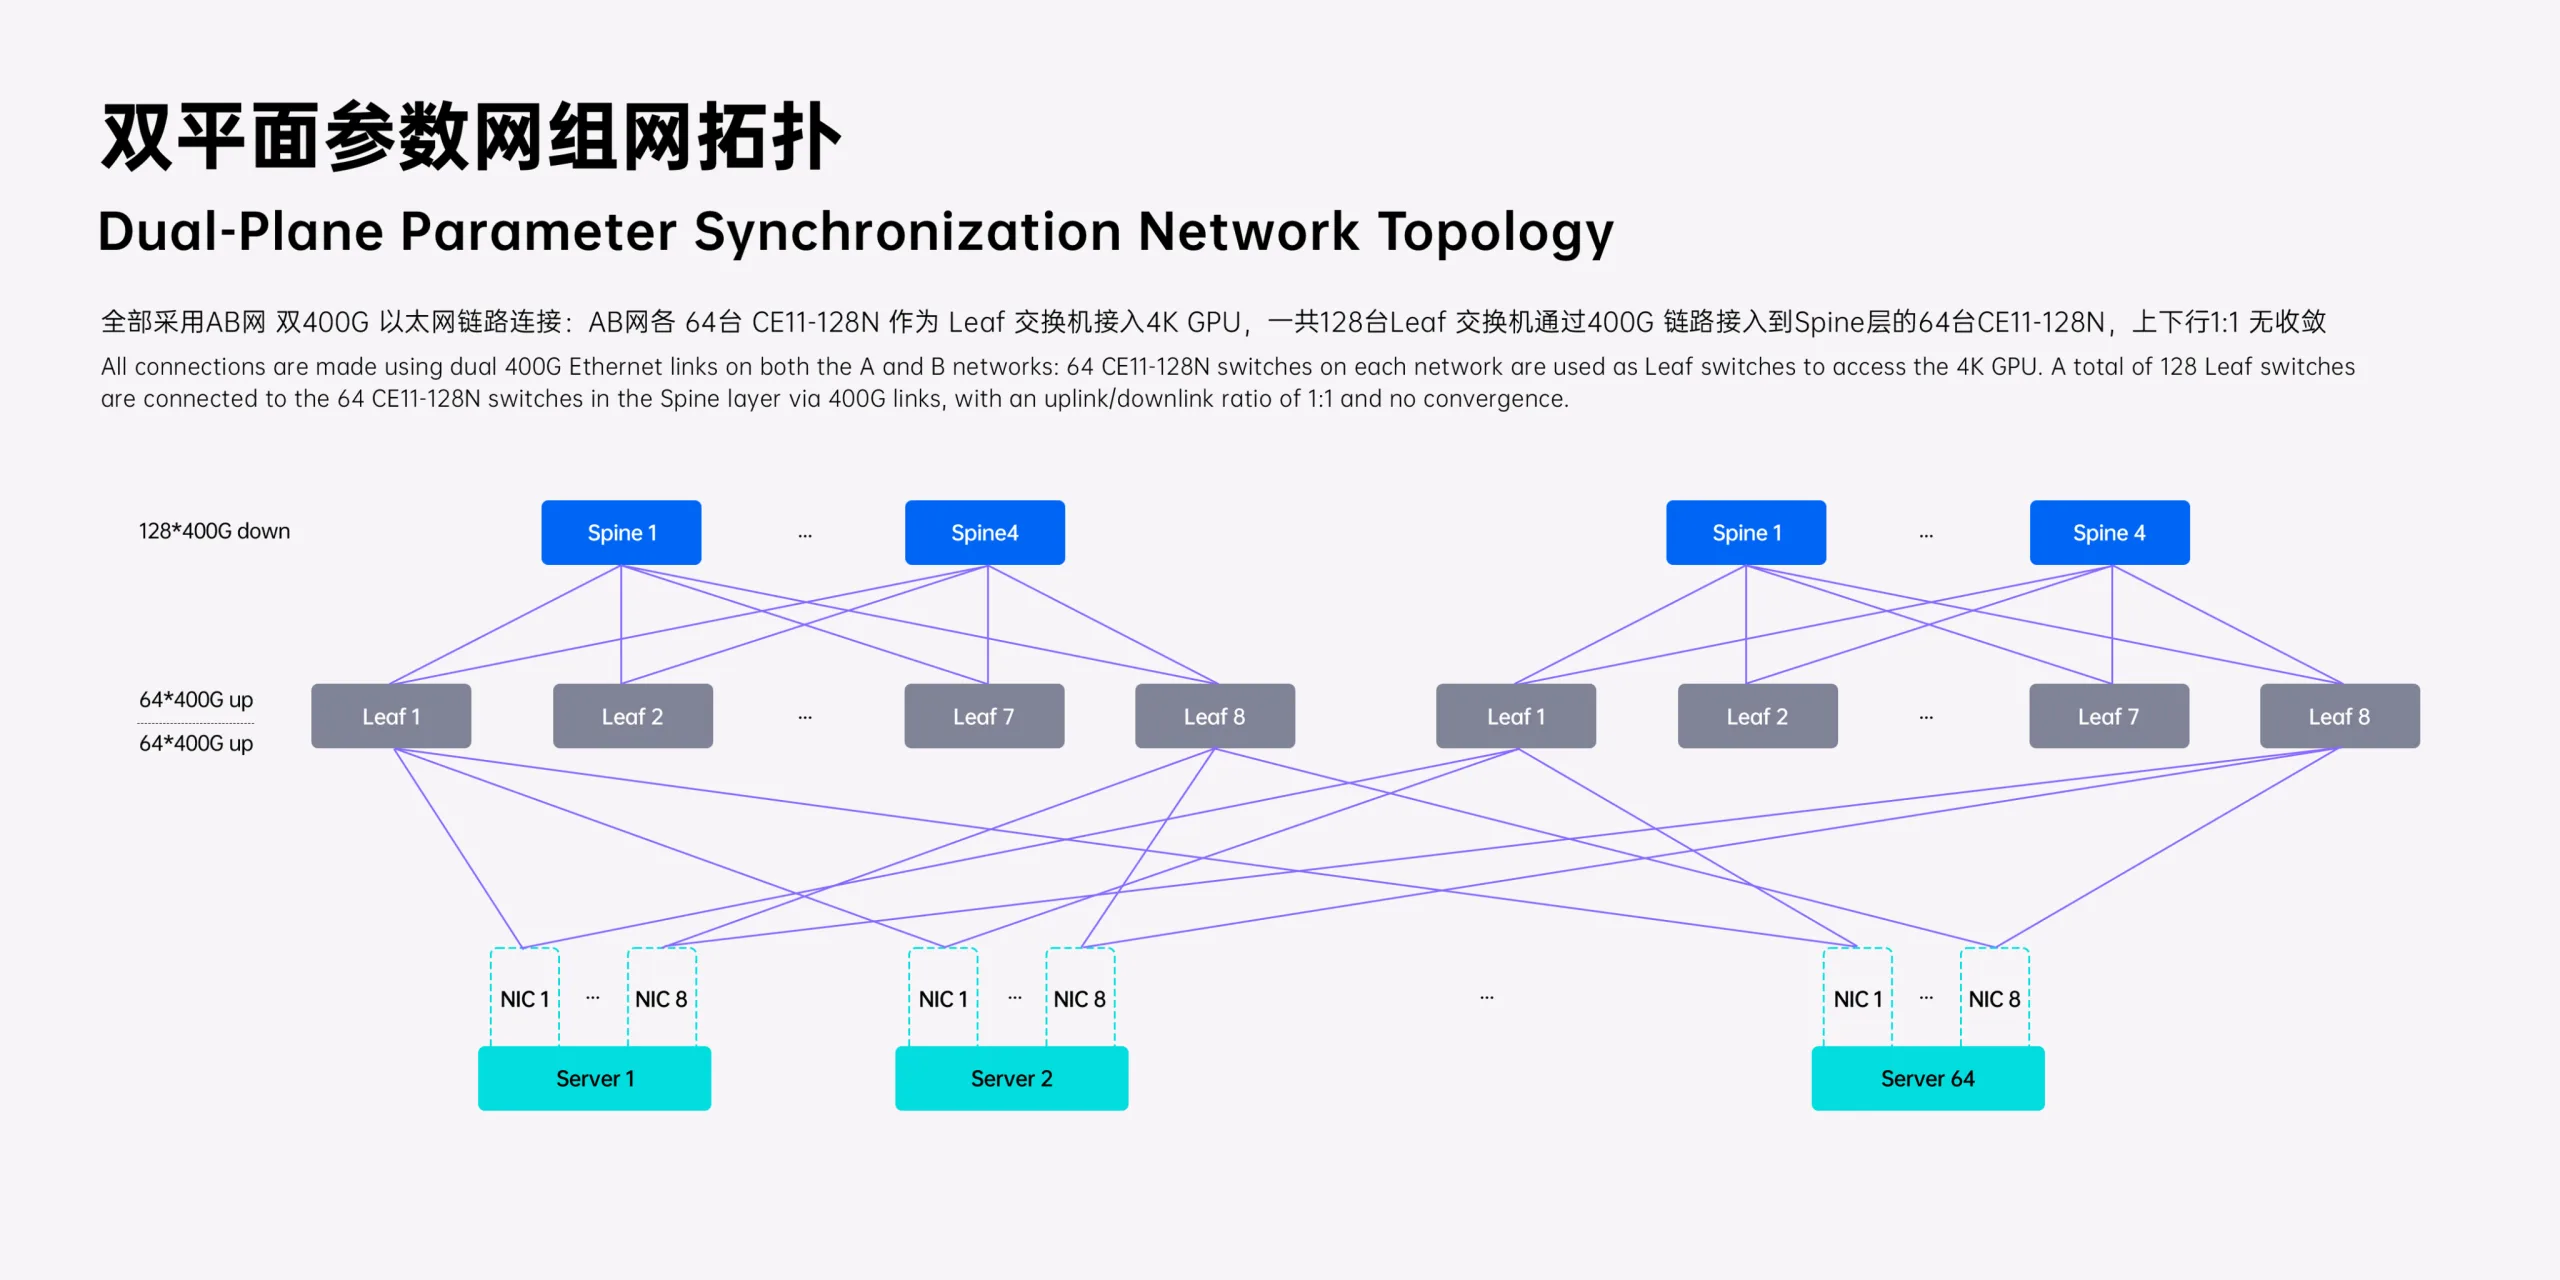
For AI training parameter synchronization at the 10,000-card scale, an AB dual-plane 400G Ethernet fully interconnected architecture is used. 128 Leaf switches connect to 4K GPU compute nodes and are interconnected via 64 Spine switches, achieving 1:1 non-blocking uplink/downlink, with dual-plane load balancing and mutual redundancy. Each server is equipped with 8 NICs for cross-plane access, ensuring high availability at both the link and device levels. It supports collective communication like AllReduce and AllGather, delivering 400G high bandwidth, microsecond-level latency, and second-leve

多平面解决方案
SUPRANETT

Let's chat about solutions?

Chaohuilian focuses on AI hyperscale cluster infrastructure, maximizing the value of each GPU.