Platforms

High-Performance Switches for AI Data Center
High-speed, reliable connectivity for large-scale AI clusters

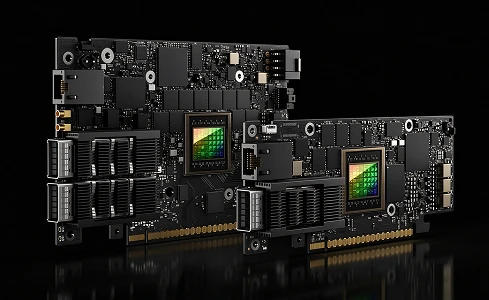
Designed for high-speed Ethernet and lossless RoCE networking, our switches deliver high bandwidth and low latency to support reliable, high-performance connectivity across large-scale AI clusters.

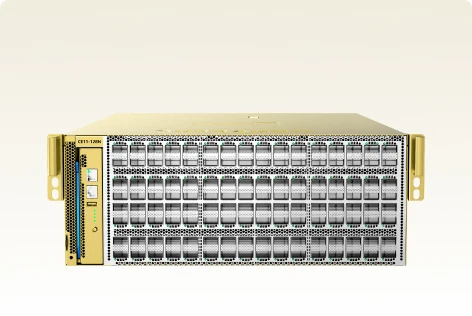
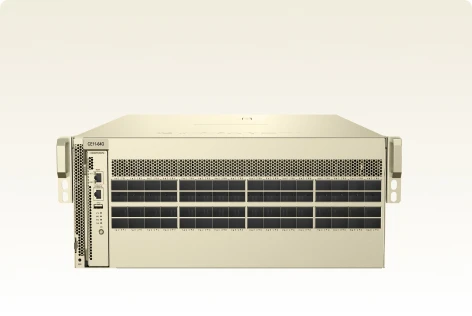
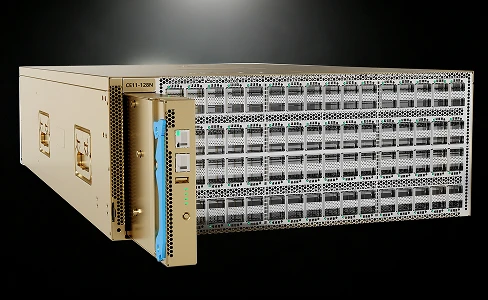
CE11-128N

AI Switch

CE11-128N

NVIDIA Spectrum-4

128 x400G

51.2Tbps

76.8Bpps

≤ 1,600W

Thousand-card-level AI training cluster

Learn more
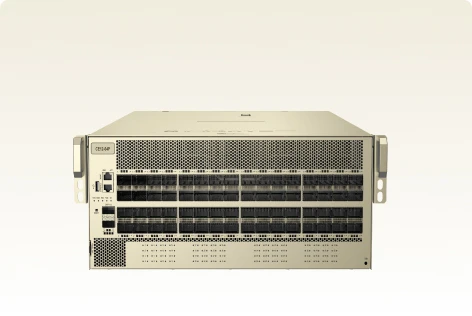
CE11-64O

AI Switch

CE11-64O

NVIDIA Spectrum-4

64 x800G

51.2Tbps

76.8Bpps

≤ 1,600W

10K-Card AI Training Cluster

Learn more
CE12-64P

AI Switch

CE12-64P

NVIDIA Spectrum-6

64 x1.6T

102.4Tbps

153.6Bpps

≤ 2,200W

100,000-Card AI Factory

Learn more
CE12-64PC

AI Switch

CE12-64PC

NVIDIA Spectrum-6

64 x1.6T CPO

102.4Tbps

153.6Bpps

/

100,000-Card AI Factory

Stay tuned.

/Highlights

Product Technology Highlights

High-Performance Forwarding Architecture

Based on the NVIDIA Spectrum high-performance chip, it delivers ultra-fast forwarding capability and ultra-low latency.

High Reliability and Availability

Multi-level redundancy design with hot-swap support for critical components, ensuring 24/7 stable business operation.

Open Ecosystem Compatibility

Fully compatible with the NVIDIA ecosystem and mainstream AI computing platforms, ensuring optimal interoperability.

Programmable and Evolvable

Supports open APIs and automated operations, evolving continuously for the future.

Network optimization design

Deeply optimized for RoCE networks, supporting lossless networking and large-scale congestion control.

Green and Energy-Saving

Efficient heat dissipation and intelligent frequency modulation design reduce energy consumption and enhance the energy efficiency ratio.

/Using Scence

application scenario

01

Inference Service Cluster

Efficient heat dissipation and intelligent frequency modulation design reduce energy consumption and enhance the energy efficiency ratio.

02

AI Factory

Deeply optimized for RoCE networks, supporting lossless networking and large-scale congestion control.

03

Large model training cluster

Supports open APIs and automated operations, evolving continuously for the future.

SUPRANETT

Let's chat about solutions?

Chaohuilian focuses on AI hyperscale cluster infrastructure, maximizing the value of each GPU.